In one paragraph
Comparisons of sentiment classifiers are often decided by evaluation practice rather than by the models: vectorizers fitted on test data, a fixed decision threshold, or accuracy reported on a corpus where one class holds 93 percent of the documents. This work evaluates eight model families (naive Bayes, logistic regression, a calibrated linear SVM, random forest, XGBoost, a soft-voting ensemble, a CNN and a BiLSTM) across five representations (counts, TF-IDF, Word2Vec, Doc2Vec, token sequences) on three corpora (racist and sexist tweet detection, COVID-19 vaccine tweets, IMDB reviews) under one leakage-free protocol: representations fitted per cross-validation fold, decision thresholds and model selection from out-of-fold predictions, one scoring pass on the held-out split. The benchmark ships as a maintained system with experiment tracking, model cards, a prediction service over PostgreSQL, drift monitoring, CI, Docker and cloud infrastructure definitions. Every number on this page is regenerated from saved predictions.
Key findings
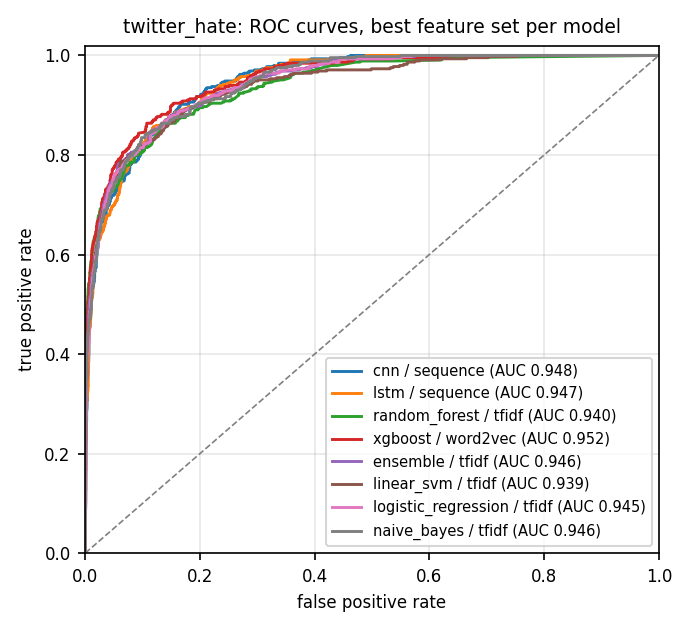
ROC-AUC of every model family on the hate-speech task. They rank tweets almost equally well.
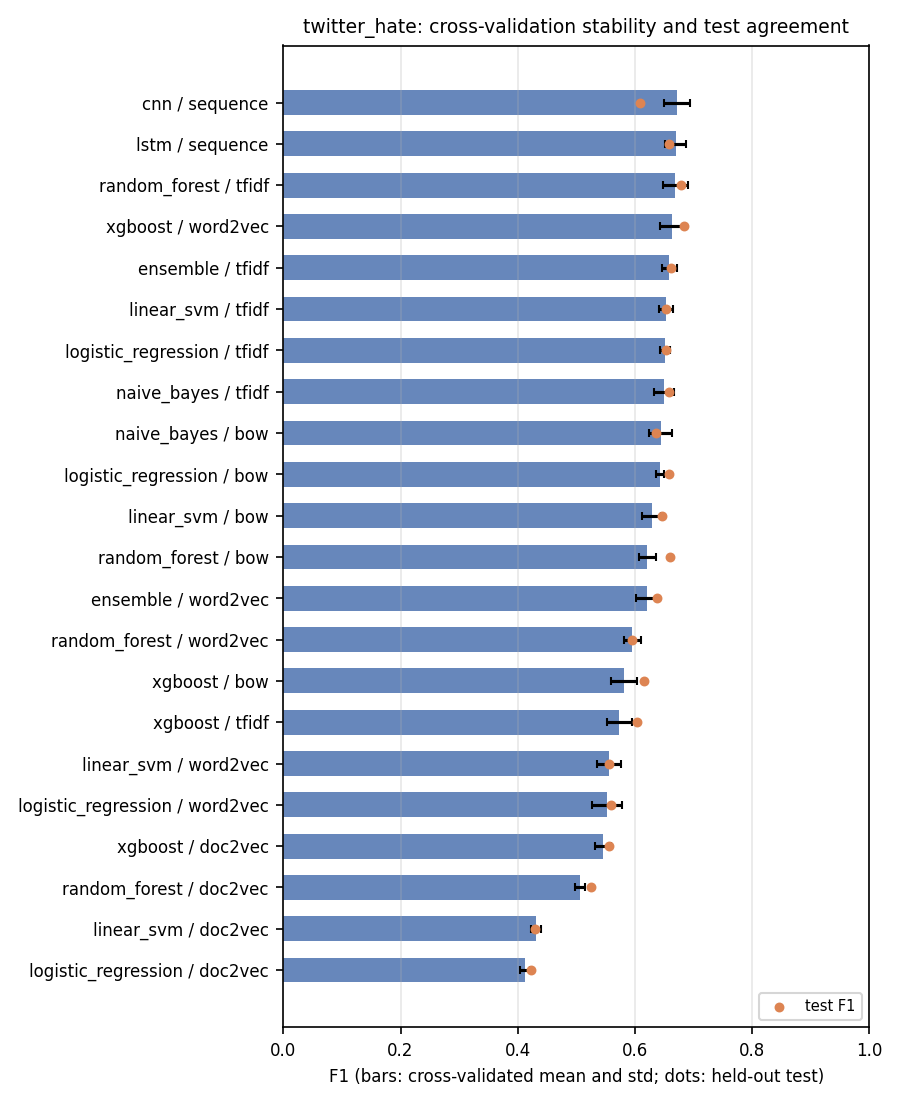
Their F1 on the positive class. The spread is calibration and threshold transfer, not ranking ability.
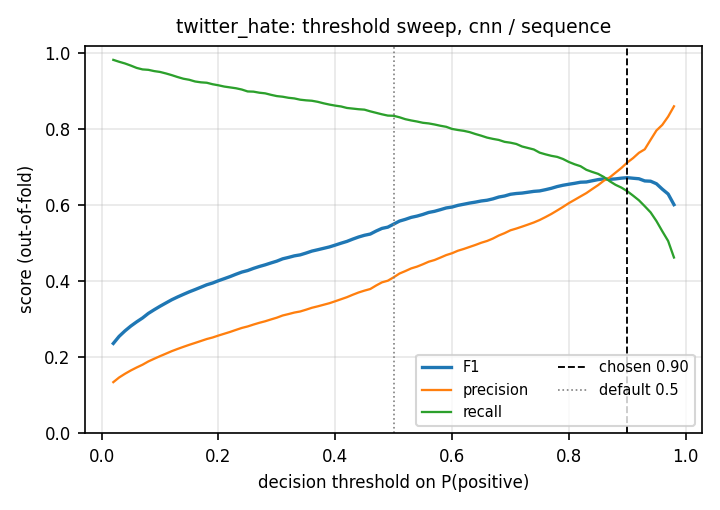
F1 gained by tuning the threshold on out-of-fold predictions instead of using 0.5 (classical models / networks).
Corpus x representation x model, each under the same protocol, each tracked, each regenerable.
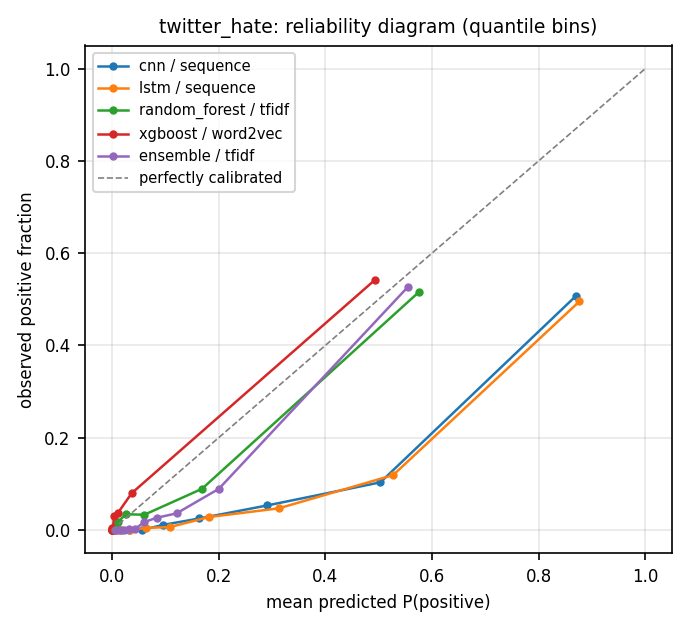
- Over-confident networks transfer thresholds worst. The CNN has the best cross-validated F1 on the hate corpus (0.672) but scores 0.608 on the test split; calibrated linear and tree models reproduce their cross-validated F1 within 0.02.
- Sparse n-grams beat learned document embeddings on tweets. Doc2Vec is the weakest representation for every model on both Twitter corpora; Word2Vec helps trees and hurts linear models.
- On long balanced reviews, linear models are the ceiling. Logistic regression, the calibrated SVM and their ensemble reach F1 0.884 to 0.888 on IMDB; the CNN and BiLSTM trained from scratch do not, at a hundred times the cost.
- The 2022 study was directionally right and numerically wrong. Its ranking of classical models survives the protocol; its headline "94 percent accuracy" was the majority-class rate on a leaky split.
Selected model per corpus
Selection uses cross-validated F1 on the training split only; the test split is scored once. F1 is on the positive class for binary tasks and macro-averaged for the three-class task.
| Corpus | Train / test | Selected model | Test F1 | Accuracy | ROC-AUC | Best classical model |
|---|---|---|---|---|---|---|
| Hate speech (Twitter) | 25,569 / 6,393 | CNN on sequence | 0.608 | 0.955 | 0.948 | Random forest on TF-IDF: 0.680 |
| Vaccine sentiment (Twitter) | 8,282 / 2,071 | CNN on sequence | 0.812 | 0.859 | 0.948 | Logistic regression on counts: 0.775 |
| IMDB reviews | 25,000 / 25,000 | Linear SVM (calibrated) on TF-IDF | 0.884 | 0.882 | 0.953 | Linear SVM (calibrated) on TF-IDF: 0.884 |
Every model family at its best representation (test F1)
| Model | Hate speech | Vaccine | IMDB |
|---|---|---|---|
| Naive Bayes | 0.658 (TF-IDF) | 0.698 (counts) | 0.851 (TF-IDF) |
| Logistic regression | 0.654 (TF-IDF) | 0.775 (counts) | 0.886 (TF-IDF) |
| Linear SVM (calibrated) | 0.654 (TF-IDF) | 0.744 (counts) | 0.884 (TF-IDF) |
| Random forest | 0.680 (TF-IDF) | 0.709 (counts) | 0.859 (TF-IDF) |
| XGBoost | 0.684 (Word2Vec) | 0.757 (counts) | 0.865 (TF-IDF) |
| Soft-voting ensemble | 0.662 (TF-IDF) | 0.757 (TF-IDF) | 0.888 (TF-IDF) |
| CNN | 0.608 (sequence) | 0.812 (sequence) | 0.875 (sequence) |
| BiLSTM | 0.658 (sequence) | 0.779 (sequence) | 0.876 (sequence) |
Figures
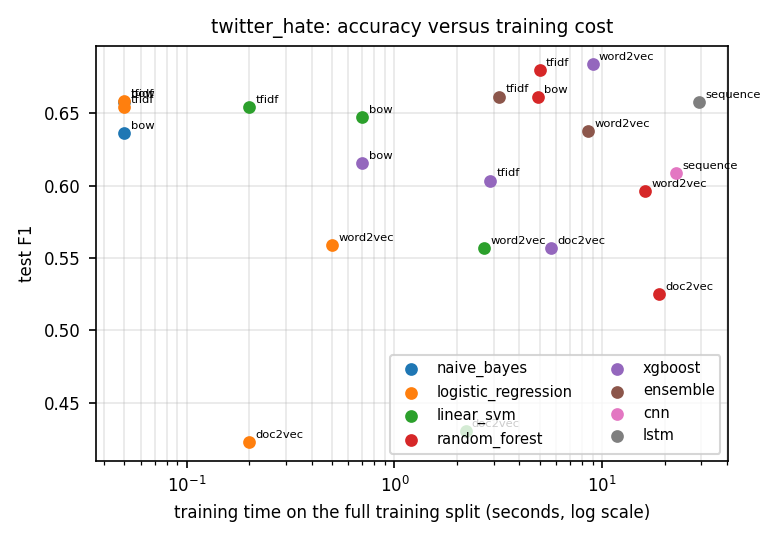
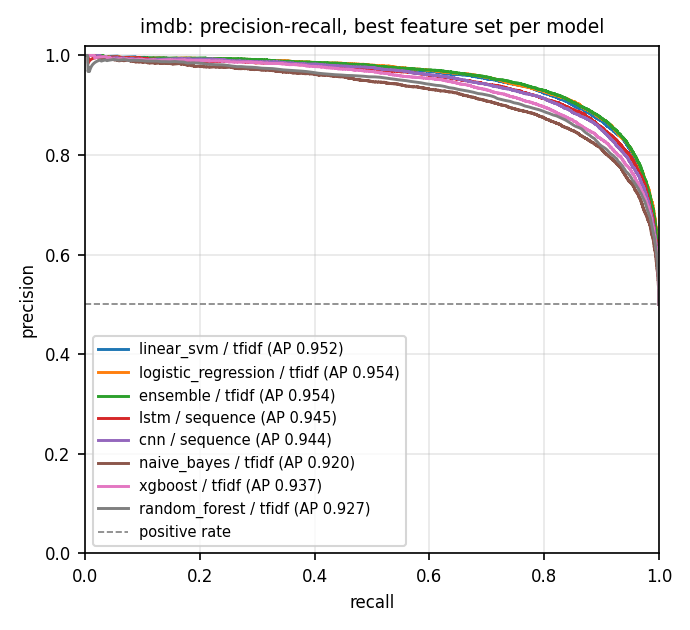
Thirty figures in total (ROC, precision-recall, reliability, threshold sweeps, cross-validation stability, heatmaps, efficiency, per-class scores and confusion matrices for every corpus) are in the thesis and in the repository.
Method in brief
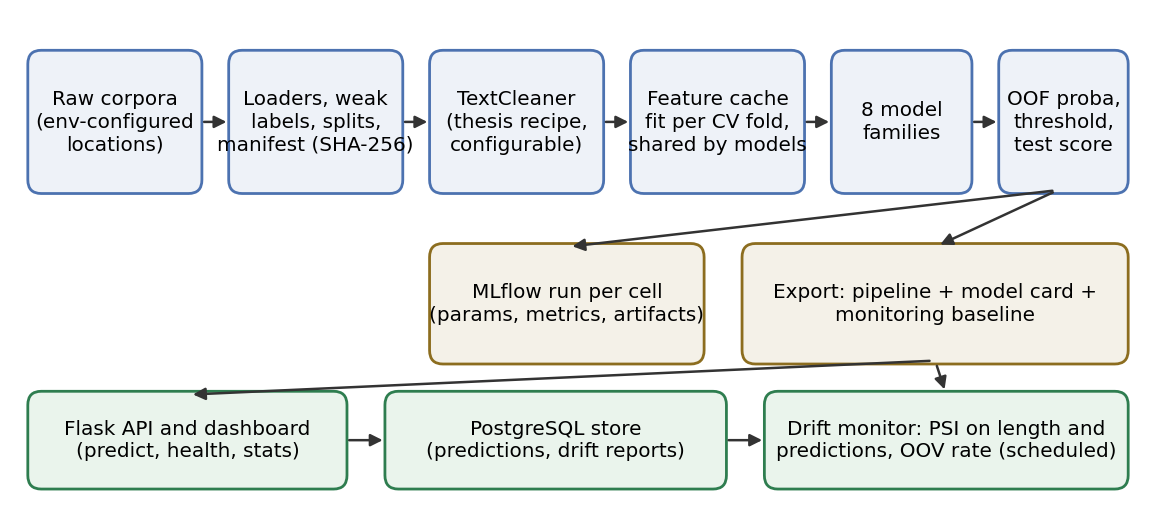
- One YAML file defines the experiment: corpora, cleaning, representations, models, grid, folds, seed. It is logged with every run.
- The training split is cleaned once; each representation is fitted per cross-validation fold and shared by every model on that fold, so models are compared on identical inputs and nothing is fitted on validation or test documents.
- Out-of-fold probabilities determine the decision threshold (binary tasks) and the selected model. The test split is scored once, at that threshold.
- Each cell is an MLflow run; the selected pipeline is exported with a model card and a monitoring baseline.
- A Flask service predicts from the exported pipelines and logs to PostgreSQL; a drift monitor compares recent traffic with the baseline (population stability index, out-of-vocabulary rate) and stores its reports.
Documents
- Paper (journal-article length, IEEE style): read online. PDF available from the author on request.
- Thesis (monograph): background and a 2026 literature review, corpora, methodology with formal definitions, system design, all experiments, discussion, future work, appendices with every benchmark cell, reproduction commands and a model card. read online.
- Code: https://github.com/rhs2/sentiment-ml-benchmark. Both documents are generated from the same results table by scripts, so no number is typed by hand.
Citation
Sium, R. H. (2026). Ranking is not the problem: Leakage-free benchmarking of sentiment classifiers on Twitter and IMDB [Project page and source code]. Nanjing University of Information Science and Technology. https://rhs2.github.io/sentiment-ml-benchmark/
@misc{sium2026ranking,
  author       = {Sium, Rakibul Hasan},
  title        = {Ranking Is Not the Problem: Leakage-Free Benchmarking of
                  Sentiment Classifiers on Twitter and IMDB},
  year         = {2026},
  howpublished = {Project page and source code},
  url          = {https://rhs2.github.io/sentiment-ml-benchmark/},
  note         = {Extends the author's BSc thesis, Nanjing University of
                  Information Science and Technology, 2022}
}
Prior work: Sium, R. H. (2022). Research on machine learning classification algorithms: A comprehensive theoretical survey of sentiment analysis and deep learning approaches [Bachelor's thesis, Nanjing University of Information Science and Technology].